Projects

Open a card for the full write-up: what I built, how I tested it, the results, and what went wrong.

BeforeAfterDevelopment (60) · Before: 56.7%56.7%Development (60) · After: 85.0%85.0%Development (60)Held out (24) · Before: 29.2%29.2%Held out (24) · After: 66.7%66.7%Held out (24)
The gain held on hard questions written before any tuning.

Project 1

Text-to-SQL Guardrails

Ask a database in English, Arabic or Urdu without trusting the model that writes the SQL.

What I didBuilt end to end: the pipeline, the guardrails and the evaluations.

BM25: 92%92%BM25Embeddings: 89%89%EmbeddingsHybrid: 95%95%Hybrid
Hybrid finds the right chapter more often than either retriever alone.

Project 2

BookMind

RAG over a book where every answer sentence is checked against its evidence.

What I didBuilt end to end: retrieval, answers, the answer checker and the evaluations.

Jul 16: 8.3Jul 16Aug 16: 15.1Sep 16: 22.5Oct 16: 17.3Oct 16Nov 16: 69.969.9Dec 16: 19.6Jan 17: 23.6Jan 17Feb 17: 19Mar 17: 28.7Apr 17: 22.2Apr 17May 17: 36.4Jun 17: 27.9Jul 17: 12.4Jul 17Aug 17: 20.7Sep 17: 5.8Oct 17: 21.6Oct 17Nov 17: 295.6295.6Dec 17: 17.3Jan 18: 20.9Jan 18Feb 18: 122.2Mar 18: 100.8Apr 18: 15.7Apr 18May 18: 21.4Jun 18: 0Jul 18: 0Jul 18Aug 18: 0
White Friday 2017 alone is 31% of 26 months of completed revenue.

Project 3

Pakistan E-Commerce Pipeline

584,524 order items from an Excel export that was 44% blank padding, accounted for row by row.

What I didBuilt end to end: ingestion, Spark jobs, warehouse, tests and CI.

what the model saidwhat happenedperfectly calibratedwhat I measuredthe gap
Every confidence band sits below the diagonal. Jev's top band, scored 0.94, was right 33% of the time.

Project 4

Does Jev's Confidence Mean Anything?

A vendor calls its confidence scores calibrated. I audited them against human annotators for $0.05, then shipped the fix as a one-file tool.

What I didRan the audit, then wrote the tool that fixes what it found.

This model: 85.8%85.8%This modelBest earlier cited: 68.78%68.78%Best earlier cited
The model scores 17 points above the best earlier result in our report, but the two numbers are not like for like.

Final-year project, 2024

Table Tennis Stroke Classifier

A fine-tuned video transformer that names the stroke in a clip, served as an API, with its limits written down.

What I didFinal-year project: fine-tuned the model and built the API around it.

What went wrong

25 things broke across the five projects: 17 fixed, 4 accepted as a documented risk, 4 still open. Each one says how it showed up and what I did.

Project
Outcome
FIXEDsql-guard

The first question of every session timed out

How it surfaced
The request timeout was shorter than a cold start. Loading the model and reading the prompt took 128 seconds, the 120 second limit cut it off, and the client retried.
What I did
Timeouts now come from measured latency, the server reads the prompt once at startup, and the model stays loaded while the server runs.
FIXEDsql-guard

Valid queries with a subquery were blocked

How it surfaced
The validator reported a derived table's alias as undefined, so valid queries with a subquery in a join were rejected. Hard questions use them often.
What I did
Derived tables are resolved like CTEs. Their contents are still checked, so naming a subquery cannot hide an unknown table.
FIXEDsql-guard

The repair loop coached an attack

How it surfaced
Asked to fix a parse error that contained DROP, the model returned the same attack with a semicolon in it. The second statement did not parse, so it vanished from the telemetry.
What I did
A rejected reply that contains a write keyword is never repaired, and the stacked-statement check uses sqlglot's tokenizer, which works on text that does not parse.
FIXEDsql-guard

A clarification lost to the Urdu verb

How it surfaced
After choosing "all orders", the Urdu question still came back filtered on status = 'delivered'. The plain-language steps under the answer showed it at once.
What I did
Clarification hints now say what to do in the query. The model then followed the chosen option in 15 of 15 tries across three languages.
FIXEDsql-guard

Stopping the demo threw the model's work away

How it surfaced
A keep-alive request sent on shutdown did not carry the context size the model was loaded with, so Ollama reloaded the model and a running job paid a 4.5 minute re-read.
What I did
The server keeps the model warm through its normal request path and never sends a bare keep-alive.
FIXEDsql-guard

A 200 MB reply passed every control

How it surfaced
Probing with printf('%.*c', 200000000, 'x') returned a 200 MB string in 1.1 seconds. It was one row, well inside the 5 second budget, an allowed function and an ordinary SELECT.
What I did
Every limit bounded rows or time and none bounded bytes. A per-cell cap and a total byte budget now apply in the executor.
ACCEPTED RISKsql-guard

Stored prompt injection through sampled column values

How it surfaced
Column values are rendered into the prompt, and repair hints quote values from the data. A value of '; DROP TABLE t-- reached the prompt intact.
What I did
A content allowlist withholds unsafe values from both. A plain-language payload cannot be filtered by form, so that residual risk is documented and a test asserts it.
FIXEDbookmind

Concept maps were built, then deleted

How it surfaced
Word co-occurrence graphs, and graphs from LLM-extracted triples over a truncated prompt, gave readers nothing they could act on.
What I did
I removed the feature. A shipped graph nobody can use costs more than the feature is worth.
FIXEDbookmind

The first test set could not tell two retrievers apart

How it surfaced
With only 12 questions, a single question moved Recall@5 by 8 points, so no comparison between retrievers meant anything.
What I did
I grew the set to 38 answerable and 4 off-topic questions, written and committed before dense or hybrid retrieval was measured so they could not be tuned to the new code.
FIXEDbookmind

Each retriever failed in a different way

How it surfaced
BM25 matches words, so it misses a passage that says the same thing differently. Embeddings match meaning but drift toward passages that are merely on the same topic, and they are worse at exact terms.
What I did
Run both and merge the rankings with Reciprocal Rank Fusion, which uses only ranks, so the two score scales never need to be reconciled.
ACCEPTED RISKbookmind

The smallest local model copied instead of answering

How it surfaced
qwen2.5:0.5b answered in 17 seconds, but it pasted the retrieved passage back instead of answering the question.
What I did
The default stays on the 7b model. If no model is reachable, an extractive fallback returns the top passage with its citation and says so.
FIXEDpk-pipeline

Spark split 11 rows into 22 broken records

How it surfaced
The row-count check between ingest and Spark failed. Eleven SKUs contain line breaks inside quotes, so Spark turned each of those rows into two broken records.
What I did
The CSV reader now sets multiLine. Raw files are immutable, so the fix was replayed from the original data rather than patched downstream.
FIXEDpk-pipeline

grand_total would have counted a 3-item order three times

How it surfaced
grand_total is the order total repeated on every item, so summing it overstates revenue for every multi-item order.
What I did
Revenue is computed per item as price × qty − discount, and the fact table has one row per order item.
FIXEDpk-pipeline

9,713 discounts were larger than the item they discounted

How it surfaced
Profiling found lines whose discount exceeds price × quantity, which gives negative revenue.
What I did
Those rows go to quarantine with the reason code DISCOUNT_EXCEEDS_LINE, visible and reprocessable, instead of being dropped or silently clamped.
FIXEDpk-pipeline

The object store vanished two weeks before the build

How it surfaced
The project was designed on MinIO. MinIO deleted its images from Docker Hub on 11 September 2026.
What I did
Because the code only speaks the S3 API, switching to RustFS was a one-line change in docker-compose.yml, and so is moving to AWS.
ACCEPTED RISKpk-pipeline

The security review found vulnerable jars

How it surfaced
The Postgres JDBC driver 42.7.4 had three HIGH CVEs, and the AWS SDK bundle 1.12.262 shipped old Jackson, Ion and Netty with 19 HIGH or CRITICAL CVEs.
What I did
Upgraded to JDBC 42.7.13, which has no known CVEs, and SDK 1.12.797. Twelve findings remain, all in shaded Netty, and are written up as an accepted risk until a Spark 4 upgrade.
ACCEPTED RISKpk-pipeline

Data quality fell off a cliff in January 2018

How it surfaced
Quarantined rows jump from a handful a month to between 257 and 2,934 a month. That looks like a change in the source system.
What I did
Nothing to fix upstream. The quarantine table makes the change visible, measurable and reprocessable instead of silently dropped.
FIXEDjev-audit

My first guess at a better prompt made it worse

How it surfaced
Mirroring the annotators' own published definition, which should have been the fairest wording, gave the highest ECE of four wordings (0.519).
What I did
I ran four wordings of the same question in one call over identical state, so only the phrasing varied, then re-ran the whole pipeline with the best wording instead of the first. The bias survived.
FIXEDjev-audit

Accuracy would have said the model was fine

How it surfaced
At a 2.9% base rate, flagging nothing scores 97.1% accuracy, so accuracy on this data is worse than useless.
What I did
The measuring step prints the do-nothing baseline before anything else and reports precision and recall.
FIXEDjev-audit

ECE can be gamed

How it surfaced
A model that ignores its input and returns the base rate for every row scores a perfect ECE of 0.0000 with AUC 0.5.
What I did
jevcal prints that baseline beside your result and makes its own decisions on Brier score, which cannot be gamed that way.
FIXEDjev-audit

Invented data could be mistaken for real data

How it surfaced
A no-API-key mode needs simulated data to test the plumbing, and simulated data looks exactly like data.
What I did
Simulated output goes to separate SIMULATED files and every chart is stamped, so the two cannot be confused.
STILL OPENtt-strokes

A confident wrong answer is still a confident answer

How it surfaced
The softmax score is not calibrated, so a wrong prediction can come back with a very high score and look exactly like a right one.
What I did
Not fixed here. It is documented as a limitation, and the Jev audit and jevcal are my follow-up work on measuring and correcting exactly this.
STILL OPENtt-strokes

Look-alike strokes blur together

How it surfaced
Loops are sometimes confused with hits, and serve spin types (sidespin, topspin and backspin) with each other.
What I did
Not fixed. Pose estimation with MediaPipe is on the roadmap.
STILL OPENtt-strokes

The training data is one facility from one angle

How it surfaced
The clips are player-centred videos from a single sports facility, so the model may generalise poorly to overhead, broadcast or behind-the-player views.
What I did
Not measured and not fixed. I say so here instead of implying robustness.
STILL OPENtt-strokes

The API shipped without tests

How it surfaced
The service works, but nothing in the repo asserts that it keeps working.
What I did
Tests for the API are the first open item on the roadmap.

How I check my work

  • 28pass
  • 19fail
  • 8unclear

55 claims tested across the five projects. The failures are in there too, and each project page says what went wrong.

Every number links to the file it came from, pinned to a commit. A script re-checks all 119 of them before this site is published, so a wrong number stops the deploy.

sql-guard
bookmind
pk-pipeline
jev-audit
tt-strokes

Ask my work

Type a question about my projects. It searches this site and shows the passages it found and where they came from. Ask it something unrelated and it says it does not know. There is no chatbot behind it, so it cannot make things up.

Try
Break it

Answers appear here, with the passage and where it came from. Off-topic questions should be refused.

Does it work? I wrote 48 questions to tune its refusal rule and held 17 more out of the tuning. On the held-out ones: the right project was in the top 3 for 11 of 11 answerable questions (MRR 1), 6 of 6 off-topic questions were refused, and 1 answerable ones were wrongly refused. 158 passages, no external service.

Earlier work

Smaller projects from before the five above. No test results for these, just what they are and where the code is.

  1. Computer vision

    Traffic Sign Detector

    A CNN reaches 97% and a fine-tuned ResNet50 reaches 99.26% on the German Traffic Sign Benchmark: over 50,000 images across 40+ sign classes, trained on a Colab GPU.

    CNNResNet50Google ColabJupyter
    Source on GitHub ↗
  2. NLP

    Sarcasm Detection

    An SVM classifier over sentiment features: SentiWordNet common-sense expansion, sentence-level sentiment shifts and reduced n-grams. Scored on accuracy, precision, recall and F1.

    PythonSVMSentiWordNetNLP
    Source on GitHub ↗
  3. C++ application

    Cricket Statistics System

    Logs matches and scores, tracks player statistics such as runs, wickets and averages, and aggregates them into team performance.

    C++
    Source on GitHub ↗
  4. C application

    Pharmacy Management System

    Inventory tracking, prescription storage with search, billing and customer records, written in C.

    C
    Source on GitHub ↗
  5. Mobile app

    NU Chat Messenger

    A WhatsApp-style messenger built with Flutter and Firebase: realtime messaging, authentication, media sharing and group chats.

    FlutterFirebase
    Source on GitHub ↗
  6. Web app

    Book Buddy

    A booking app for event tickets, hotels and movie showtimes, built with React on a MySQL backend.
    ReactMySQLJavaScript
    Source on GitHub ↗

About me

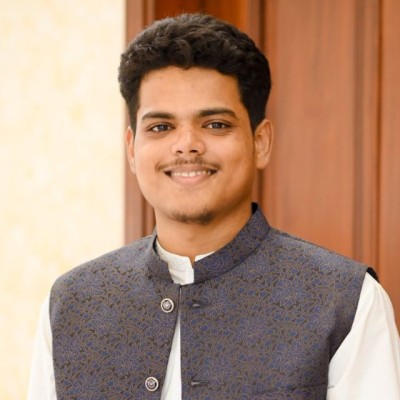
Portrait of Adil Muhammad Pervez

I'm Adil, an AI engineer in Karachi with two years of industry experience at US and UAE AI companies (Turing, CNTXT AI), building RLHF preference data and training datasets for frontier LLMs and computer vision models.

I build production-style LLM applications in Python (RAG pipelines, SQL agents with guardrails) with evaluation harnesses and CI gates, and I fine-tune transformer models with PyTorch and Hugging Face.

It shapes how I work: decide what "working" means, try to break it, and publish the numbers, including the bad ones.

Based in
Karachi, Pakistan
Education
BS Computer Science, National University of Computer and Emerging Sciences (FAST-NUCES), Sept 2020 – June 2024
Focus
LLM evaluation, RAG, text-to-SQL guardrails, data pipelines

Experience

  • LLM Evaluation Engineer

    Turing

    Contract · United States, remote · Mar 2026 – Jun 2026

    • Generated RLHF preference data in Turing's post-training pipeline used to align frontier LLMs.
    • Scored model responses on math, logic and domain reasoning against rubrics, feeding the reward signal.
    • Analyzed model failure modes and edge cases, documenting rationales that drove training-data fixes.
  • AI Data Quality Engineer

    CNTXT AI

    United Arab Emirates, remote · Jun 2024 – Jan 2026

    • Evaluated medical and legal LLM outputs for accuracy and safety, flagging hallucinations and policy breaches.
    • Validated large-scale text, image and video datasets for LLM and computer vision training.
    • Identified systematic failure patterns and edge cases, improving dataset reliability for downstream models.
LLMs and agentsLangChain, LangGraph, AI agents, tool calling, RAG, prompt engineering, LLM APIs
LLM evaluation and dataEval harnesses, guardrails, hallucination detection, RLHF and preference data, CI gates
ML and deep learningPyTorch, Hugging Face Transformers, fine-tuning, computer vision, NLP, Recall@k, MRR
EngineeringPython, FastAPI, REST APIs, SQL (PostgreSQL, SQLite), Pandas, Docker, Git, GitHub Actions, pytest